Kepub vs EPUB: what Kobo actually changes
Somewhere in the first month of owning a Kobo, most people meet a file called
something.kepub.epub and ask the question that keeps resurfacing on
MobileRead’s forums: what is this, and should my own books be one? The kepub
vs EPUB question sounds like a format war. It is not. A kepub is an EPUB —
same ZIP container, same manifest, same chapters — with one renamed extension
on the outside and one layer of added markup on the inside.
We publish browser-based EPUB tools, so instead of repeating folklore we did the direct thing: took the small specimen EPUB this site uses for all its tests, applied Kobo’s transformations to it by hand, and measured what changed. This post is that measurement.
.kepub.epub so the device routes it to that engine. Nothing about
the container changes — our hand-built kepub still passes EPUB validation.
One extension, two rendering engines
A Kobo device carries two renderers, and the filename decides which one your
book gets. Kobo’s own publisher documentation, the
Kobo EPUB spec, spells the switch
out: a sideloaded file left as .epub renders in the Adobe Digital Editions
WebKit, while renaming it to .kepub.epub “triggers the Kobo WebKit” — the
same engine store-bought books use. Fixed-layout titles have a third spelling,
.fxl.kepub.epub.
The same document is refreshingly blunt about the trade-off for sideloaders: files carrying the kepub extension “will disable bookmarking and note keeping”, and cover thumbnails “may not display”. Otherwise, it says, the reading experience is identical to a store copy. That sentence is written for publishers testing content before sale, and it is the closest thing to an official word on what a sideloaded kepub can and cannot do.
So the extension is a routing decision, not a conversion. What makes a real kepub different is what sits inside the chapters.
What a kepub adds under the lid
Three things, all of them additions. The cleanest public record of them is kepubify, the open-source converter whose transform code documents each step as matching official store kepubs — and whose source we read, rather than guessed at, for this post.
First, every chapter’s body is wrapped in two divs,
div#book-columns > div#book-inner, which give Kobo’s engine a stable target
for its pagination styles. Second, a small style element with the id
kobostylehacks is added to each chapter’s head. Third — the signature move —
every sentence of visible text is wrapped in its own span. Here is chapter 1
of our specimen after the transform, with the original text untouched inside
the new markup:
<body><div id="book-columns"><div id="book-inner">
  <h1><span class="koboSpan" id="kobo.1.1">CHAPTER 1: WHAT THIS FILE IS</span></h1>
  <p><span class="koboSpan" id="kobo.2.1">This is the specimen book Epub Studio
  uses to demonstrate its own tools. </span><span class="koboSpan"
  id="kobo.2.2">It was written for that purpose and for no other; …</span></p>
The id scheme is kobo.paragraph.sentence, counted per chapter file: the
heading above is paragraph 1, the first paragraph’s two sentences are
kobo.2.1 and kobo.2.2. Images get a paragraph number of their own.
kepubify’s source states the purpose plainly: the spans give the engine
addressable chunks of text, and highlighting, bookmarking “and other related
features don’t work without this”. Kobo’s spec says the same thing from the
store’s side — its pipeline “inserts div and span tags during processing to
enable user functionality (ex. text highlighting)”, which is also why that
document warns stylists against styling bare div or span selectors: your
CSS would leak onto markup Kobo added after you.
If the idea of a book being a pile of addressable XHTML is new, the anatomy is laid out in our tour of what is inside an EPUB — a kepub adds to that structure without replacing any of it.
We built one, and the validator does not blink
Talk is cheap, so we reimplemented those three transforms in a short script
and ran them over specimen.epub, the 5,183-byte test book this site’s
screenshots all use. The results, chapter by chapter:
| Chapter file | Before | After spans |
|---|---|---|
| chapter-001.xhtml | 364 B | 568 B |
| chapter-002.xhtml | 845 B | 1,225 B |
| chapter-003.xhtml | 905 B | 1,373 B |
| chapter-004.xhtml | 618 B | 954 B |
| chapter-005.xhtml | 573 B | 865 B |
| whole book | 5,183 B | 5,775 B |
Every added byte is markup; the sentences themselves are byte-identical. The
container did not change either — the mimetype entry still sits stored,
uncompressed, at byte 38, exactly where the EPUB spec wants it.
Then the real test: we dropped the finished specimen.kepub.epub on this
site’s own validator, which checks the container declaration, manifest and
spine like any strict reader would.
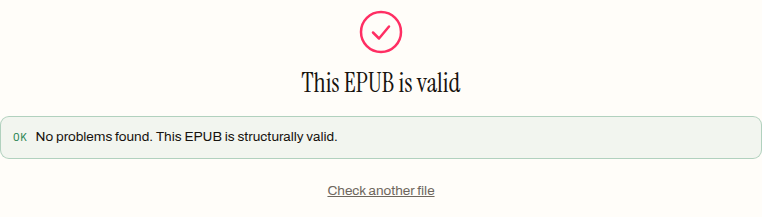
“No problems found. This EPUB is structurally valid.” That is the headline
fact of the whole comparison: kepub is not a rival format that things must be
converted out of. It is EPUB wearing extra markup that other reading systems
simply ignore — which is also why a kepub renamed back to .epub opens
anywhere an EPUB does.
Converting your own books: when and how
For a book you only ever read outside Kobo hardware, converting buys you nothing but 11% more markup. On a Kobo, the case for converting a sideloaded book is that it puts your file in front of the same engine, with the same anchoring markup, as a store copy — with the sideloading caveats Kobo’s own documentation states and we quoted above.
The route that works today: check the EPUB is structurally sound, convert with kepubify, copy the result to the device over USB, and keep the double extension intact — the steps are recapped at the end of this post. The validation step earns its place because the conversion is a parse of your XHTML: kepubify makes a point of tolerating malformed markup (its README claims conversions “in a fraction of a second (40–80x faster than Calibre)” and graceful handling of bad HTML — its numbers, not ours), but a book that is broken enough misrenders in strict engines with or without spans. We have seen where that road goes in EPUB compatibility problems, and one pass through our EPUB validator before converting is the cheap insurance.
When not to convert is just as clear-cut. If bookmarking and notes on sideloaded books matter to you, remember the spec’s warning that the kepub extension disables both for sideloaded files. If your books come from the Kobo store, they already went through Kobo’s processing and need nothing from you. And if a book carries DRM, conversion tools are the wrong conversation entirely — the lock is separate from the format, and removing it is not something we help with.
What we can and cannot prove from here
Being realistic about this: there is no Kobo on the desk this run. Everything above rests on three legs — Kobo’s published spec, kepubify’s source code, and the measurements we took on our own fixture. That covers the mechanism and the container completely, and it covers device behaviour only as far as Kobo’s own documentation describes it. Firmware moves; if your Kobo treats a sideloaded kepub differently from the spec’s description, trust the device in your hands over the document.
The comparison on the Amazon side of the fence is structurally similar and twice as messy — a family of dialects rather than one — and we mapped it in the Kindle file format guide. Kobo’s dialect, by contrast, turns out to be a remarkably light touch: same book, same container, one engine switch, and a span around every sentence doing quiet anchoring work underneath your highlights.
How to convert an EPUB to kepub for a Kobo
- 01 Validate the EPUB firstRun the file through an EPUB validator. The kepub conversion parses your XHTML and inserts markup into it, so a structurally broken book should be fixed before, not after.
- 02 Convert with kepubifyPoint kepubify at the .epub and it writes a .kepub.epub next to it, with the spans, wrapper divs and style hook added.
- 03 Copy it to the Kobo over USB, keeping the double extensionDrag the .kepub.epub file into the device's storage. The name must keep both parts — the extension is what routes the book to Kobo's own engine.
- 04 Open it and spot-check a chapterConfirm the book opens and a long chapter reads normally. If anything renders oddly, the plain .epub copy still works on the device the ordinary way.
Frequently asked questions
Is a kepub still a valid EPUB?
Yes. A kepub keeps the same ZIP container, the same mimetype file, the same package manifest and spine. The one we built for this post went through our validator afterwards and came back with no problems found. The changes are additions inside the chapter markup, not changes to the container.
Can other reading apps open a .kepub.epub file?
Generally yes, because underneath it is an ordinary EPUB. The extra spans and wrapper divs are legal XHTML that other engines simply ignore. If an app refuses the double extension, renaming the file back to .epub gives it the same bytes under the name it expects.
Does converting to kepub change the book's text?
No. The conversion wraps each sentence in a span element; it does not rewrite, reflow or re-encode the sentences themselves. On our specimen the whole book grew by 592 bytes, all of it markup. The words are byte-for-byte the ones the EPUB carried.
Can I just rename my .epub to .kepub.epub without converting?
The rename alone does switch Kobo's rendering engine, because the extension is the trigger. But none of the span markup will exist inside, and Kobo's engine anchors its text features to those spans. Renaming without converting gets you the engine while withholding the markup the engine's features hang off.
Are books bought from the Kobo store kepubs?
Kobo's publisher documentation says the store pipeline inserts these div and span tags during processing, so a store copy carries the same kind of markup a converter adds. Store books also normally carry DRM, which is a separate lock on top of the format and not something any converter should touch.